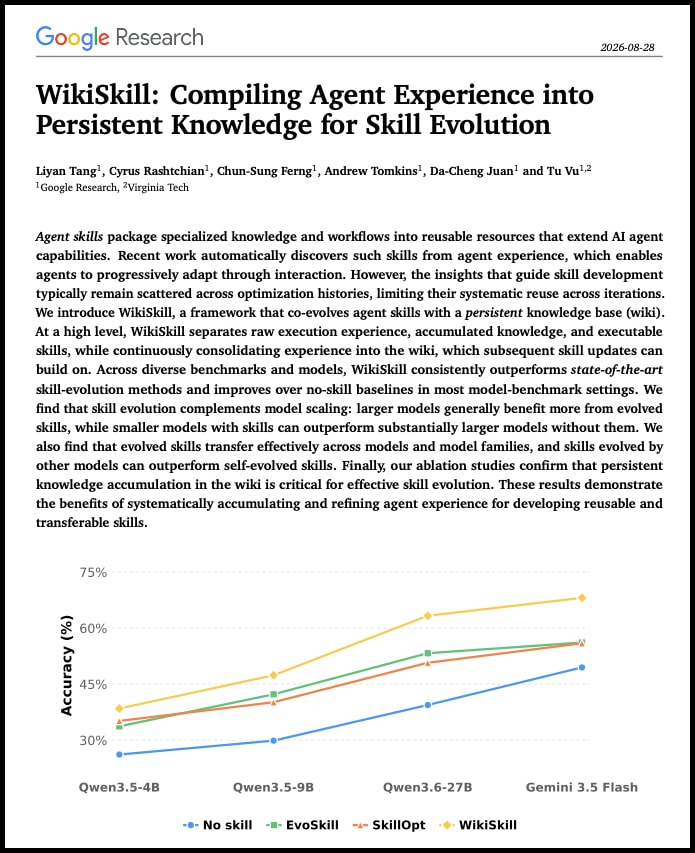
@nate_512The graph in that Google paper is what got me. Qwen-9B with evolved skills posts 47.4% across five benchmarks. Qwen-27B running bare posts 39.4%. Both Qwen, neither one fine-tuned. Smaller model wins. What skill evolution actually does: the agent takes a swing at a task, reads back its own traces, rewrites its own skill set, and keeps the rewrite only when validation says it helped. EvoSkill, SkillOpt, Trace2Skill all trip on the same thing, the lessons worth keeping end up buried in optimizer history instead of anywhere reusable. WikiSkill's fix is a wiki that lives between the traces and the skills. Karpathy's LLM Wiki is the inspiration. After every run a maintainer sorts the wins and the misses into that wiki, a proposer reads it and edits SKILL.md, and anything that turns out bad rolls back on its own. Numbers back it. WikiSkill clears the best prior method by 3.3 to 12.0 points on all five models tested. The bigger the model the more it gains: 12.3 points on Qwen 4B, 17.5 on 9B, 23.9 on 27B. Skills also travel. Qwen-27B wrote them, Qwen-9B picked them up, SpreadsheetBench went 24.3% to 50.5%. And the wiki is not decorative. Take it out and Gemini 3.5 Flash falls from 63.7% to 48.7%. Most skills out there are still written by hand. A bigger model is not the only way up. Test what evolved skills squeeze out of the one you already own first
Orijinal gönderiyi gör