Qwen 3.6 35B on MacBook Pro M5 Max
yazan Estebankiwi: Qwen
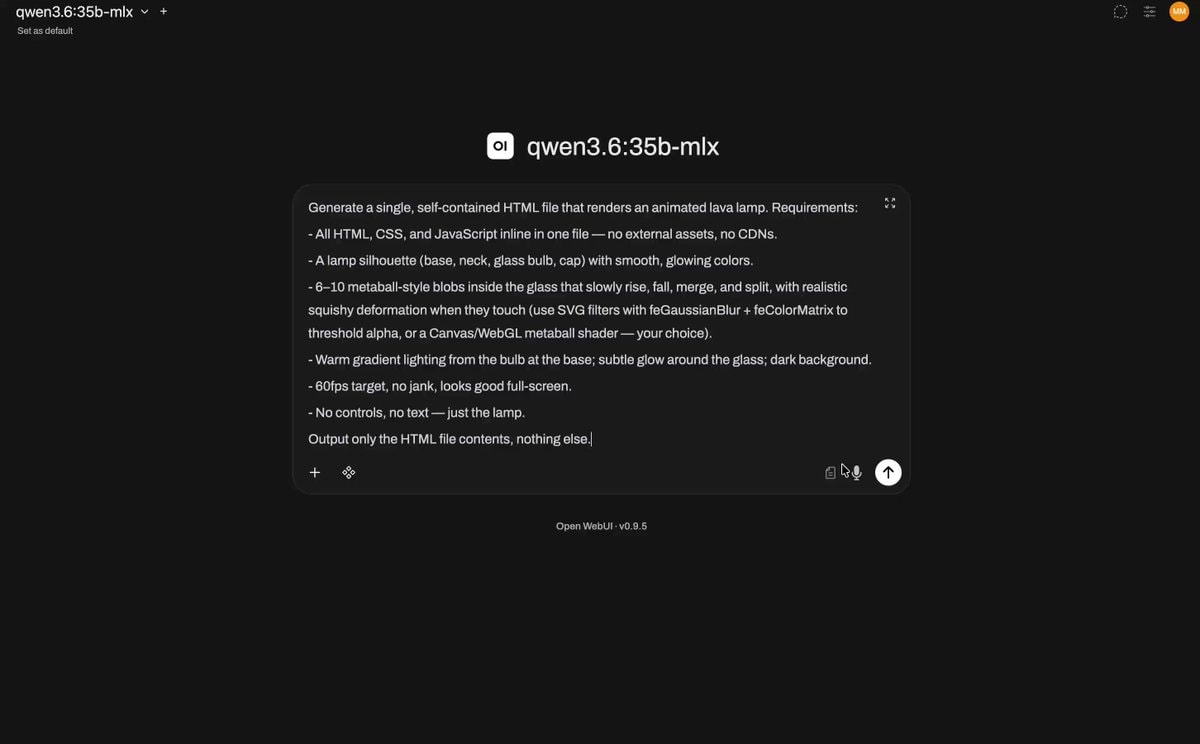
Qwen 3.6 35B is achieving more than 100 tokens per second on my $5,399 MacBook Pro M5 Max. This counts as the best local AI model I have ever run. It uses 128GB of unified memory. There is no cloud involved. No API costs apply. No rate limits exist. It delivers raw local inference at speeds I did not think were possible on a laptop. This model proves more intelligent than GPT 5 on benchmarks. It runs locally. On a MacBook. For free after the hardware cost. I once said local AI would never compete with frontier models. I am starting to rethink that. The gap is closing faster than anyone expected. The focus is a text box with a detailed description of a task. It involves generating an HTML file for an animated lava lamp. The text outlines specific requirements like the inclusion